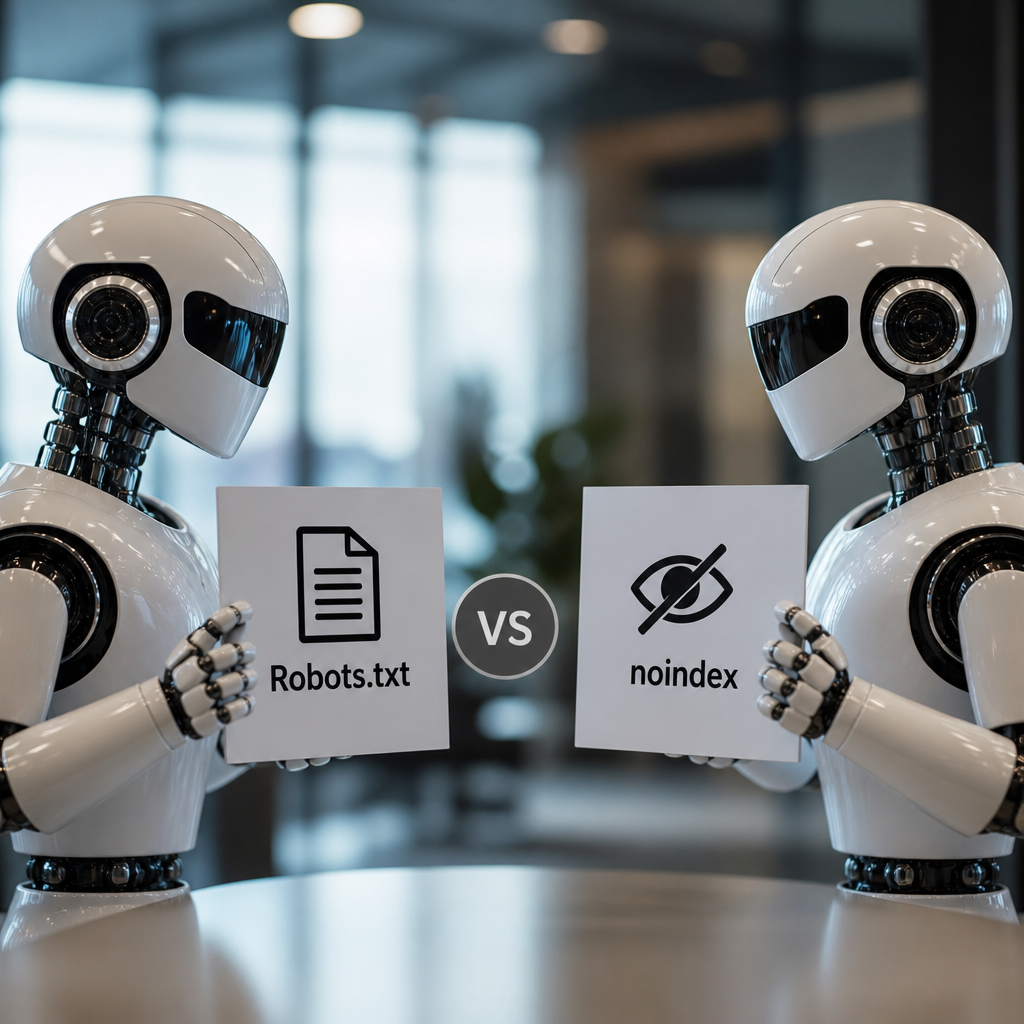
Hiding a URL from search results is not just about making it less visible. It's important to distinguish crawl control from display control in the index. These two mechanisms serve different purposes, and confusing them can leave a page accessible in the results when you thought you had removed it.
The robots.txt file tells robots which areas of the site they can crawl. The meta directive with noindex, on the other hand, requests that a page searchable by robots not be kept in the results. The right choice therefore depends on your actual intention: to limit robot requests, remove a URL from the engine, or protect sensitive content.
Understand the difference between crawling and indexing
Crawling corresponds to robots visiting your URLs to read their content. Indexing then occurs: the engine analyzes the page and decides whether or not to add it to its results database. Denying access does not automatically equate to removing a URL from the index. An address may be known through external links, a sitemap, or a previous crawl.
This nuance explains a common mistake: adding a disallow rule in robots.txt to make a page disappear from search results. If the bot can no longer load the page, it cannot read the instruction asking it not to index it. The URL may then remain visible, sometimes without a detailed description. Google recommends allowing the bot to access a page when the goal is its permanent removal from results.
When to use the robots.txt file?
The robots.txt file is placed at the root of the domain and primarily serves to organize the crawling of robots. It is relevant for technical directories, parameters generating a large number of URLs, internal search pages, or areas whose analysis provides no SEO value.
Reduce exploration of unnecessary areas
On an e-commerce site, for example, color, size, or sorting filters can generate thousands of combinations. Preventing bots from crawling some of these URLs avoids wasting server resources and helps focus analysis on strategic pages. This logic concerns the management of bot crawling paths, not the guaranteed removal of already known content.
The same reasoning applies to endless calendars, login pages, shopping carts, or non-essential scripts. However, one must remain cautious: a rule that is too broad may prevent the analysis of files useful for rendering your pages. Google specifically advises blocking only non-critical resources for understanding content and layout.
The limits to know
A robots.txt file is neither an access protection nor a privacy tool. Its content is public and its respect depends on the robot consulting it. It should therefore never be used to protect internal documents, personal data, or pages reserved for clients. For these contents, authentication is preferable.
Furthermore, the exploration ban does not guarantee that the address will never appear in a search engine. If links point to it, the engine may display the URL without being able to analyze its content. This method is therefore useful for controlling crawling, but it is not the ideal solution when the goal is the complete disappearance of a page from the results.
A question about this article?
Contact usWhen to favor the meta directive with noindex?
To remove an existing page from the results while keeping it accessible to visitors, the most suitable solution is generally an exclusion instruction placed in the page's code. It is located in the head section of the HTML document and informs compatible search engines that they should not keep this URL in their index.
This option is suitable for thank-you pages after a form, test content, internal sheets, less useful archives, printable versions, or sorting pages. Internet users who have the link can still view them, but they are no longer intended to attract organic traffic. The page must remain accessible to the bot, without blocking in the robots.txt file, so that the instruction is detected.
The case of PDFs, images, and other files
A meta instruction can only be added to an HTML page. For a PDF, image, video, or other file, the appropriate solution is to send an X-Robots-Tag HTTP header containing noindex. This method extends index control to non-HTML resources, without having to modify their content.
She often requests the intervention of a developer or server configuration. Before applying it to a set of files, check the exact scope: removing a useful document, a product image, or a downloaded resource can have consequences on visibility and user experience.
Which method to choose according to your objective?
The choice becomes simple as soon as the intention is clearly formulated. Use robots.txt when you want to avoid unnecessary requests on certain areas, particularly dynamic or technical URLs. Use noindex when the page should remain available but no longer appear in search results.
- For a private page: set up password access or remove the content.
- For a deleted URL with no equivalent: return an HTTP 404 or 410 code.
- For a moved page with a relevant replacement: use a permanent 301 redirect.
- For accessible content not intended for search engine indexing: add a noindex instruction and allow crawling.
- For technical spaces or uninteresting filters: limit exploration via robots.txt.
A removed page should not receive the same response as a page simply excluded from results. Each status responds to a different business situation. A poorly chosen redirect, such as an exclusion applied to a high-potential page, can disrupt users and reduce organic performance.
Check the setup before making further changes
After adding a noindex instruction, removal is not always instantaneous. The engine must revisit the URL, read the information, and then update its index. Use the URL inspection tool in Search Console to check what Google actually receives. The technical check must be on the version crawled by the bot, not just on what you see in your browser.
Also analyze the indexing report and test your robots.txt rules before publishing them. Regular auditing of automated access allows for the identification of accidental blockages and URLs that unnecessarily consume crawl budget. The article on robot access auditing provides useful benchmarks for structuring this verification.
Make masking a consistent SEO decision
The best solution is not the one that blocks the most, but the one that precisely matches the role of each URL. A healthy SEO architecture distinguishes between content to promote, to explore, and to discard. This logic avoids turning technical settings into obstacles to your visibility.
In an AI-driven strategy, like the Bot To Bot approach proposed by BotLink, understanding the dialogue between your site and bots becomes essential. It's not just about hiding pages, but about helping search engines focus their attention on the right resources. To delve deeper into this topic, discover the stakes of strategic indexing.