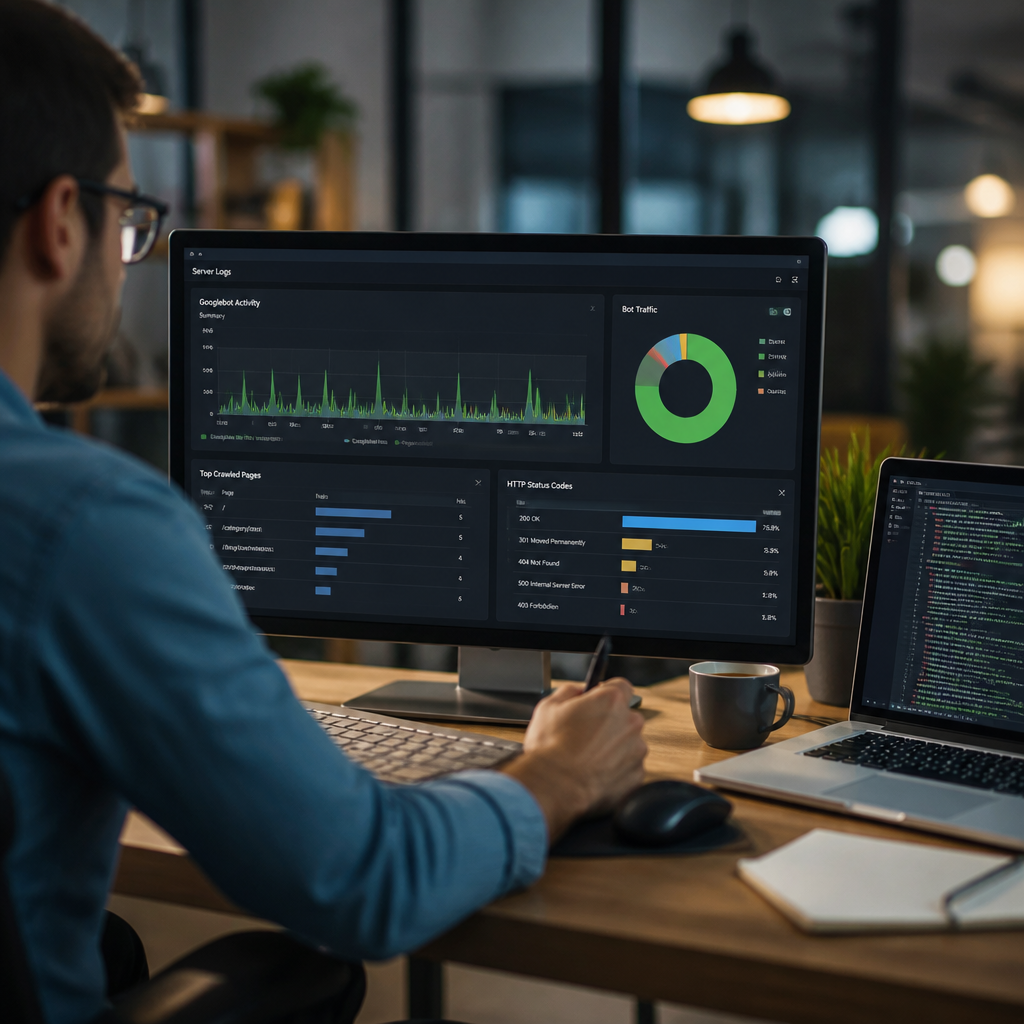
The files recorded by web hosting are a valuable source for understanding how search engine crawlers explore a site. They show the actual requests made, the pages visited, the responses received, and the frequency of visits. This ground-level perspective makes it possible to go beyond standard reports and identify the actual behavior of Googlebot on each important section.
When used effectively, these technical logs help detect ignored pages, repeated errors, or wasted resources on irrelevant URLs. The goal is not to track each request one by one, but to transform a large volume of data into actionable decisions to improve the crawling and indexing of your site.
Why examine your server logs?
Classic tracking tools often indicate which pages receive human visitors. Access logs, meanwhile, reveal what the search engine bot sees. Each line may contain a date, an IP address, a requested URL, a response code, a volume of transmitted data, and sometimes the user agent. These elements allow for reconstructing the bot’s crawling path.
This reading is particularly useful for large sites, online stores, media outlets, or platforms with many filters and URL parameters. In these environments, poor architecture can lead Googlebot to visit thousands of secondary pages while neglecting strategic content. Server data thus provide direct proof of crawl priorities.
However, it is necessary to distinguish a robot claiming to be Googlebot from a genuine Google robot. The user agent can be imitated by malicious actors or automated tools. Verification therefore involves the IP address and its domain resolution, followed by confirmation consistent with official Google domains. This step protects your study against data skewed by fake robots.
The data to be isolated before any interpretation
A raw file quickly becomes difficult to read. The first step consists of filtering requests attributed to the authenticated Google bot, then grouping URLs by their type: product pages, categories, articles, pagination pages, image files, or addresses containing parameters. This organization highlights the areas actually crawled and those that remain invisible.
Keep the essential information: date and time, requested URL, method, HTTP code, response size, potential referrer, and visit frequency. Cross-referenced with your XML sitemap and indexing data, they make it possible to identify discrepancies between the desired structure and the reality observed on the server side.
HTTP codes to monitor
The server response code is one of the most useful indicators. A 200 page is accessible, but that does not guarantee it is indexed. A 301 redirect can be healthy if it accompanies a controlled migration, whereas a redirect chain slows down crawling. 404 and 500 errors deserve priority attention because they create dead ends for bots.
The following table helps to prioritize the most frequent controls in an access log【1】…【/1】.
| HTTP code | Interpretation for the robot | Recommended action |
|---|---|---|
| 200 | Accessible content | Verify the quality and the internal linking【1】…【/1】 |
| 301 | Moved permanently | Limit successive redirects |
| 404 | Page not found | Correct the links or redirect if relevant |
| 500 | Internal server error | Intervene quickly with the technical team |
This table does not replace the study of the relevant URLs. An isolated error may be minor, whereas a daily repetition on important pages reveals a structural problem to be corrected.
A question about this article?
Contact usMeasure visit frequency and exploration depth
A strategic page should be consulted regularly, without unnecessarily monopolizing server resources. Compare the number of requests received by commercial pages, editorial content, and technical URLs. If sorting filters, internal search pages, or parameter variants concentrate activity, your crawl budget may be consumed by useless addresses.
Depth is also revealing. Content accessible several clicks from the homepage is often explored less than that linked from high-authority pages. When high-value URLs receive almost no visits from the crawler, it is advisable to review their internal linking, their presence in the sitemap, and their accessibility. A clear structure promotes more efficient crawler circulation.
To learn more about this subject, consult this audit of bot access on a site. It usefully complements the observation of requests by helping to distinguish useful bots from undesirable crawlers.
Detect the anomalies that hinder visibility
The most important signals are not always the most spectacular. A sudden drop in requests for a major section, a rise in 500 errors, or the massive appearance of URLs with parameters can reveal an incident even before organic traffic declines. It is therefore relevant to compare periods and monitor abnormal changes over time.
- Important pages never requested by Googlebot.
- Cascading redirects between multiple URLs.
- 404 errors requested repeatedly.
- Parameters generating numerous nearly identical variants.
- High response times on the most crawled pages.
When a page should not be displayed in the results, the choice between technical blocking and an exclusion directive must be consistent with your objective. The guide on choosing between robots.txt and noindex helps to better avoid contradictory decisions that complicate the work of search engines.
Implement a regular analysis method
A one-off study is useful after a redesign or a drop in visibility, but monthly monitoring provides more value. Start by exporting log files over a representative period. Then, filter out verified bots, group URLs by page template, and observe the response codes. This progressive method makes identifying technical priorities easier without getting lost in the details.
- Define the directories and page templates to monitor.
- Identify requests attributed to authenticated Googlebot.
- Classify the URLs according to their frequency and HTTP code.
- Compare the results with the site's visibility objectives.
- Correct, then measure the effect of the modifications during the next survey.
A solution such as BotLink can support this process thanks to its Bot To Bot approach, designed to facilitate exchanges between a site and Google's bots. Combined with a rigorous reading of technical logs, this approach helps to better direct natural SEO efforts and strengthen the presence of the pages that really count.
Transforming technical data into SEO decisions
The value of server logs does not lie in the accumulation of numbers. Their worth appears when they allow for action: fixing an error, simplifying a site structure, removing unnecessary links, or strengthening connections to a priority page. Every improvement must aim for more relevant site crawling, in the service of indexing and visibility.
By regularly observing Googlebot requests, you get an objective reading of your technical accessibility. This discipline makes it possible to anticipate blockages, limit crawl waste, and evolve your architecture methodically. Server logs then become a true SEO management tool, and not just a simple file reserved for technical teams.